Projects / Semantic search engine
Semantic search engine
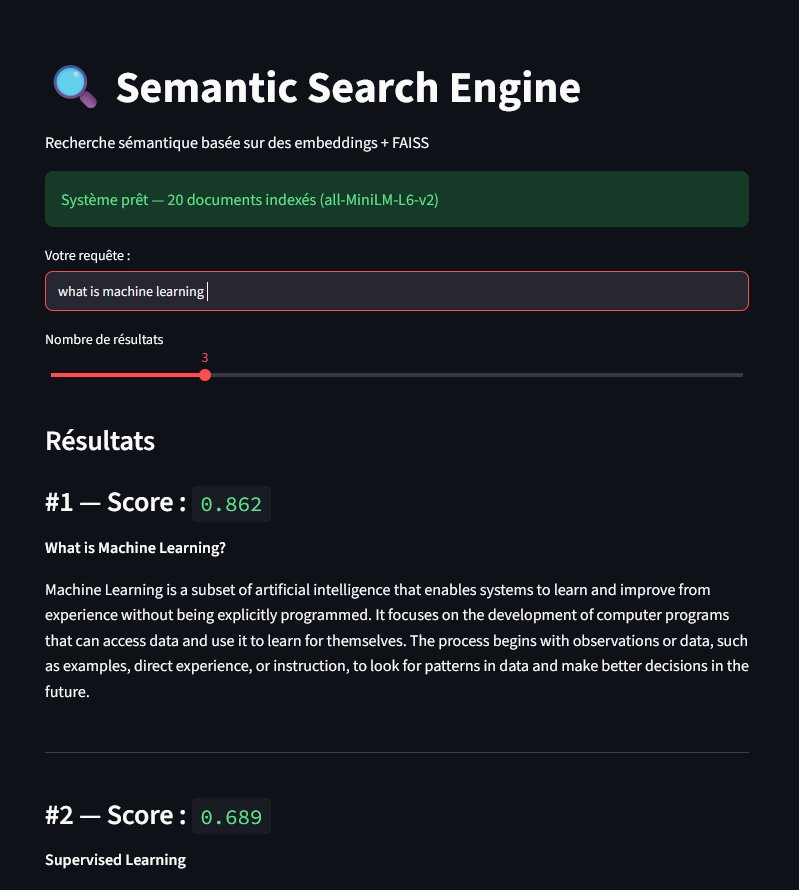
A search engine that matches queries to documents by meaning rather than by keyword overlap.
- Period
- 2026
- Type
- Personal project
- Model
- all-MiniLM-L6-v2
- Interface
- Streamlit
How it works
Documents→Sentence-Transformers 384-d embeddings→L2 normalisation→FAISS IndexFlatIP→Top-k
- Each document is encoded as a dense vector by all-MiniLM-L6-v2 (384 dimensions), then normalised.
- The vectors are stored in a FAISS IndexFlatIP index: since they are normalised, the inner product is exactly the cosine similarity, which gives readable scores between 0 and 1.
- The query is encoded the same way; FAISS returns the closest documents.
Choices and limitations
Exhaustive search is exact and sufficient at the scale of this corpus (20 hand-written documents about AI, machine learning and NLP). With hundreds of thousands of documents, an approximate index such as IVF or HNSW would be needed. The corpus can be replaced by any JSON file in the same format.
Python · Sentence-Transformers · FAISS · Streamlit